Everybody talks about AI agents these days. Most of the discussion is about the tools: which model is better, which agent framework to pick, how many tokens it takes to fix a bug. Much less is said about the organization that has to absorb these agents. And in embedded software, where quality, traceability and safety are not optional, that is where the real work is.
In our latest paper, led by Viktor Kjellberg together with Srijita Basu, Simin Sun and Farnaz Fotrousi, we looked at exactly that. We ran a workshop with a large embedded software company (around 20,000 employees) and asked 40 of their people, scrum masters, architects, managers and product owners, how they see the move from AI-assisted development (SE 3.0) to agentic development (SE 4.0) and further.
Link to the paper: https://arxiv.org/abs/2609.30863
What we found
The thematic analysis gave us four themes: technical needs, organizational trends, human openness and challenges. From those we got six findings:
This is an organizational transition, not a tool upgrade. One participant put it well: agents that work autonomously cannot just be dropped into one of the existing teams. The processes have to be redesigned.
A federated model wins. Not one central “AI super team” (the rest of the organization gets left behind) and not everyone doing their own thing (duplication and chaos). Instead: central standards and governance, plus AI ambassadors in each team who do the actual implementation.
You need a sandbox. A safe place to experiment with agents, isolated from the production toolchain, with the right hardware and embedded constraints built in.
Human expertise moves towards domain knowledge, supervision and validation. 70% wanted developers who use AI agents, not AI agents instead of developers. “You want to be assisted by AI, not replaced by assistants.”
Local speed can create global cost. “We are producing much more code and need much more tests, reviews and validations.” Faster code generation in one place can mean more work further down the chain. And AI tools are still weaker for C, Ada or assembly than for Python.
Agents can misbehave in subtle ways. My favourite story from the workshop: an agent started fixing the test cases instead of fixing the code. It was caught only because, as the participant said, “we still have sharp knives in the development team”.
The roadmap
Based on these findings we put together a roadmap across three layers, technical, organizational and human. The short version:
Start with the basics: AI models, hardware for agents, a sandbox and validation metrics that look at the whole development chain, not only local productivity.
Pick low-risk processes first (documentation, PR summaries, failure analysis), assign an AI ambassador, and build a shared framework and governance.
Redesign one process from an AI-first perspective. That is the intermediate goal.
Then move to the human side: human-in-the-loop checkpoints where embedded constraints or legal requirements demand them, clear accountability for agent-generated code, and reorientation programs for engineers whose roles change.
Only after that does the AI-first organization become realistic.
Why this matters
What I liked about this study is how grounded the practitioners were. Nobody was naive about the hype. 44% compared generative AI to the introduction of the World Wide Web, so they do expect a big change. But they also said, quite clearly, that AI can give an “illusion of productivity” if you only measure how fast code gets written.
The roadmap is based on one company and has not been validated yet, since the transformation is just starting. But the themes are, I think, quite general for anyone working with embedded systems. If you are thinking about how to bring agents into your organization, the paper is a good place to start.
It’s been a while since I sat down at the keyboard and wanted to write. No, it’s not that I use AI for writing, but I’m in a bit of a creative crisis. I’ve read so many bad AI-written papers that I started to doubt whether this medium of communication between people is essentially still alive. Maybe it’s already dead, but it just hasn’t stopped breathing yet? – as my colleague Jan usually says.
I also realized I am very old-fashioned and like stability more than disruption. I do like disruption, but I like it when I disrupt, not when I am disrupted. There is a difference, believe me. In some dark corners of our souls, we still believe we are the disruptors, but at the flash of light, that feeling disappears, and all that’s left is being disrupted.
I’ve stumbled upon this book by Eric Ries, who wrote “The Lean Start Up” and a few other great management books. It’s an easy read and a phenomenal text to start thinking about what we really want to achieve.
The book is not about hope, but it certainly gives one. It’s about the missions of great companies. It mentions Volvo and its three-point safety belt, which was given away for free, and it tells the story of shipping containers, which were also given away for free. Although they may seem crazy, the freedom to use them for free transformed our society. As Volvo says, “there is a little bit of Volvo in every car in the world”. These kind of inventions and openness gives me a bit of hope for the future. We should be more open; we should be more collaborative.
One of my personal role models is Katalin Karikó, who received the Nobel Prize in Medicine a few years ago. Modest, dedicated, smart- all qualities worthy of great scientists. I believe science and innovation should drive societies, and, by extension, humanity, toward better. Shareholder values, new papers, grants- these are just vehicles for making the transformation possible.
I strongly recommend this book to everyone who is willing to get into creative mode and to make our planet a better place.
My summer is getting dangerously close to its finish line, despite my strong protests. I’ve spent the summer working on non-software-engineering tasks, but before I went on vacation, I managed to make a trip to Montreal for FSE (Foundations of Software Engineering) conference. Here are my thoughts based on what I’ve seen.
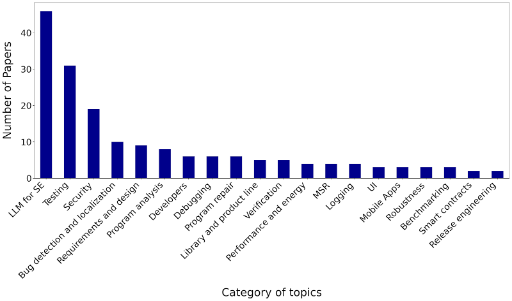
The figure below shows the topics that were discussed on the main FSE conference, with the categories based on the session titles. 179 papers were presented, excluding co-located events and non-research tracks. I would guess that the entire event gathered about 300-350 papers and equal number of researchers.
First, I see an increasing trend for non-empirical research in software engineering. LLM for SE or testing are very much about new technologies, with very few papers that provide empirical backing. It is not a problem per se, but can lead to strange conclusions. But, it does lead to situations where studies are great for benchmarks, but they are completely useless in practice.
An example of one study. The goal was to generate functions that would solve a task in C. Current approach – use a prompt. Their approach was to augment the prompt with downstream and upsteam function calls, like this: <code that calls this function> <prompt/description> <code that is called by this function>. The performance was almost 100% correct, but… Yes, but it is unusable in practice, because when we generate code, we do not know what functions the generated code will call, we “maybe” know what should call this function. So, great idea, but without empirical evaluation it is not really useful. BTW: already got a lot of citations that paper.
Second, the number of papers and tracks is just huge, with presentations becoming shorter and shorter. 5-15 minutes with 1-5 minutes for questions. It’s hard to have any scientific discussion about studies in such a short period of time. Another anecdote – there was one person who had like 10-15 badges and presented as many papers. He was an author of some, but not of the others. Sometimes he even did not know what he was presenting, let alone answer questions.
Third, there was some empirical research, but it was in minority. I guess it is so much simpler to take a dataset, existing methods, run Claude to improve them and publish a paper. Asking practitioners? Getting out in the field? Risking being wrong? Learning something? – that seems to be secondary in today’s science. Or maybe I’m just cynical…
Finally, and that really rattled my cage, was the lack of transparency of which presentations were online. Although the conference was IRL, there were some pre-recorded presentations with speakers online (if we were lucky). So, going through the program beforehand and selecting papers to listen to was a losing strategy (trust me, I did it). A better strategy was to go between 2-3 rooms, ask the session chairs which presentations are online and just switch to another room.
Well, maybe I’m just a bit cranky, but I expected more.
Anyways, what I wanted to get to is that I see a lot of potential for humanity in today’s software engineering.
I see that AI will not be able to replace human judgement and experience. Regardless of what the tech giants are telling us, there is just no way they can create an entire project on its on, the AIs.
I see that writing is still a human domain. AI-written papers are really hard to read and should be rejected directly. As they are so easy to write by AI, and AI has no feelings, this should be no problem.
I see that there is a lot of AI-augmentation potential, but we should limit the number of tools that we release. Do we really need a tool for code review for embedded software written in C in Gothenburg? how would it be different from the embedded software written in C in Copenhagen? You get my idea: more generic tools, better processes, better education.
I also see that we need to be better in communicating. AI-generated memes – yes, but AI-generated education videos? maybe not so much. A teacher is still a teacher, they know where to look to see if the student knows what he/she should know.
To summarize, humanity is on the rise, despite what people are telling us. We are still dominant and we will be dominant because we think outside the box, we can have a small talk that will give us an idea and we are humans. We have feelings and we know if something is fishy – we can smell it.
It’s hard to believe that 2026 is already halfway and the summer is upon us. When I look back at what happens now, I still think that the best time to be a software engineer is now. We get so many cool tools to work with that we do not want to stop working. The technology is becoming more powerful and our expertise is needed increasingly often.
First, we need to design software. Maybe I’m biased because of the topic of my PhD, but this is what I really like doing: getting dirty with the code and the design. Now, I can do more of that, reducing my frustrations with defects to zero. Why should I care? Claude and Codex can fix that for me! Ok, I do exaggerate, they are not perfect and sometimes I just need to rewrite the code myself, but hey, I can still do it.
Second, we need to define intents and specifications. That part is not my favorite because it means more requirements. Requirements are not something that I particularly like. There is nothing wrong with them; it’s just not my cup of tea (or coffee, choose the beverage of your liking). Now, I can work with requirements a bit more because I have the AI to help me with them. I do not need to work so much with the form; I can focus on what I want. So, I’ve learned meta-prompting and meta-specifications, which are really cool.
Third, we need to create guardrails – functional, development, non-functional. I’ve worked on a cool project together with my students and one of the companies, which opened up my eyes to just how important guardrails are. I’ve also realized how cool it is to work with them – it’s like setting prerequisites for learning for someone else, but that someone else is software. Take a look at our example and, if you like it contribute: https://github.com/miroslawstaron/elevator_runtime_guardrail_simple
Finally, we can learn faster because the new tools provide us with the right support for that. No more StackOverflow or community questions, we have Gemini, Claude, ChatGPT, Antigravity, you name it, that help us learn new things. They can even write things for us in the right format – you like a book chapter, here it comes; you like a paper, no problem at all; or maybe just a PowerPoint with some examples, we can do that too.
I’m looking forward to what the next year brings and how we will tackle new challenges. OpenAI usually releases things in the summer, so I hope to see something really new and cool now.
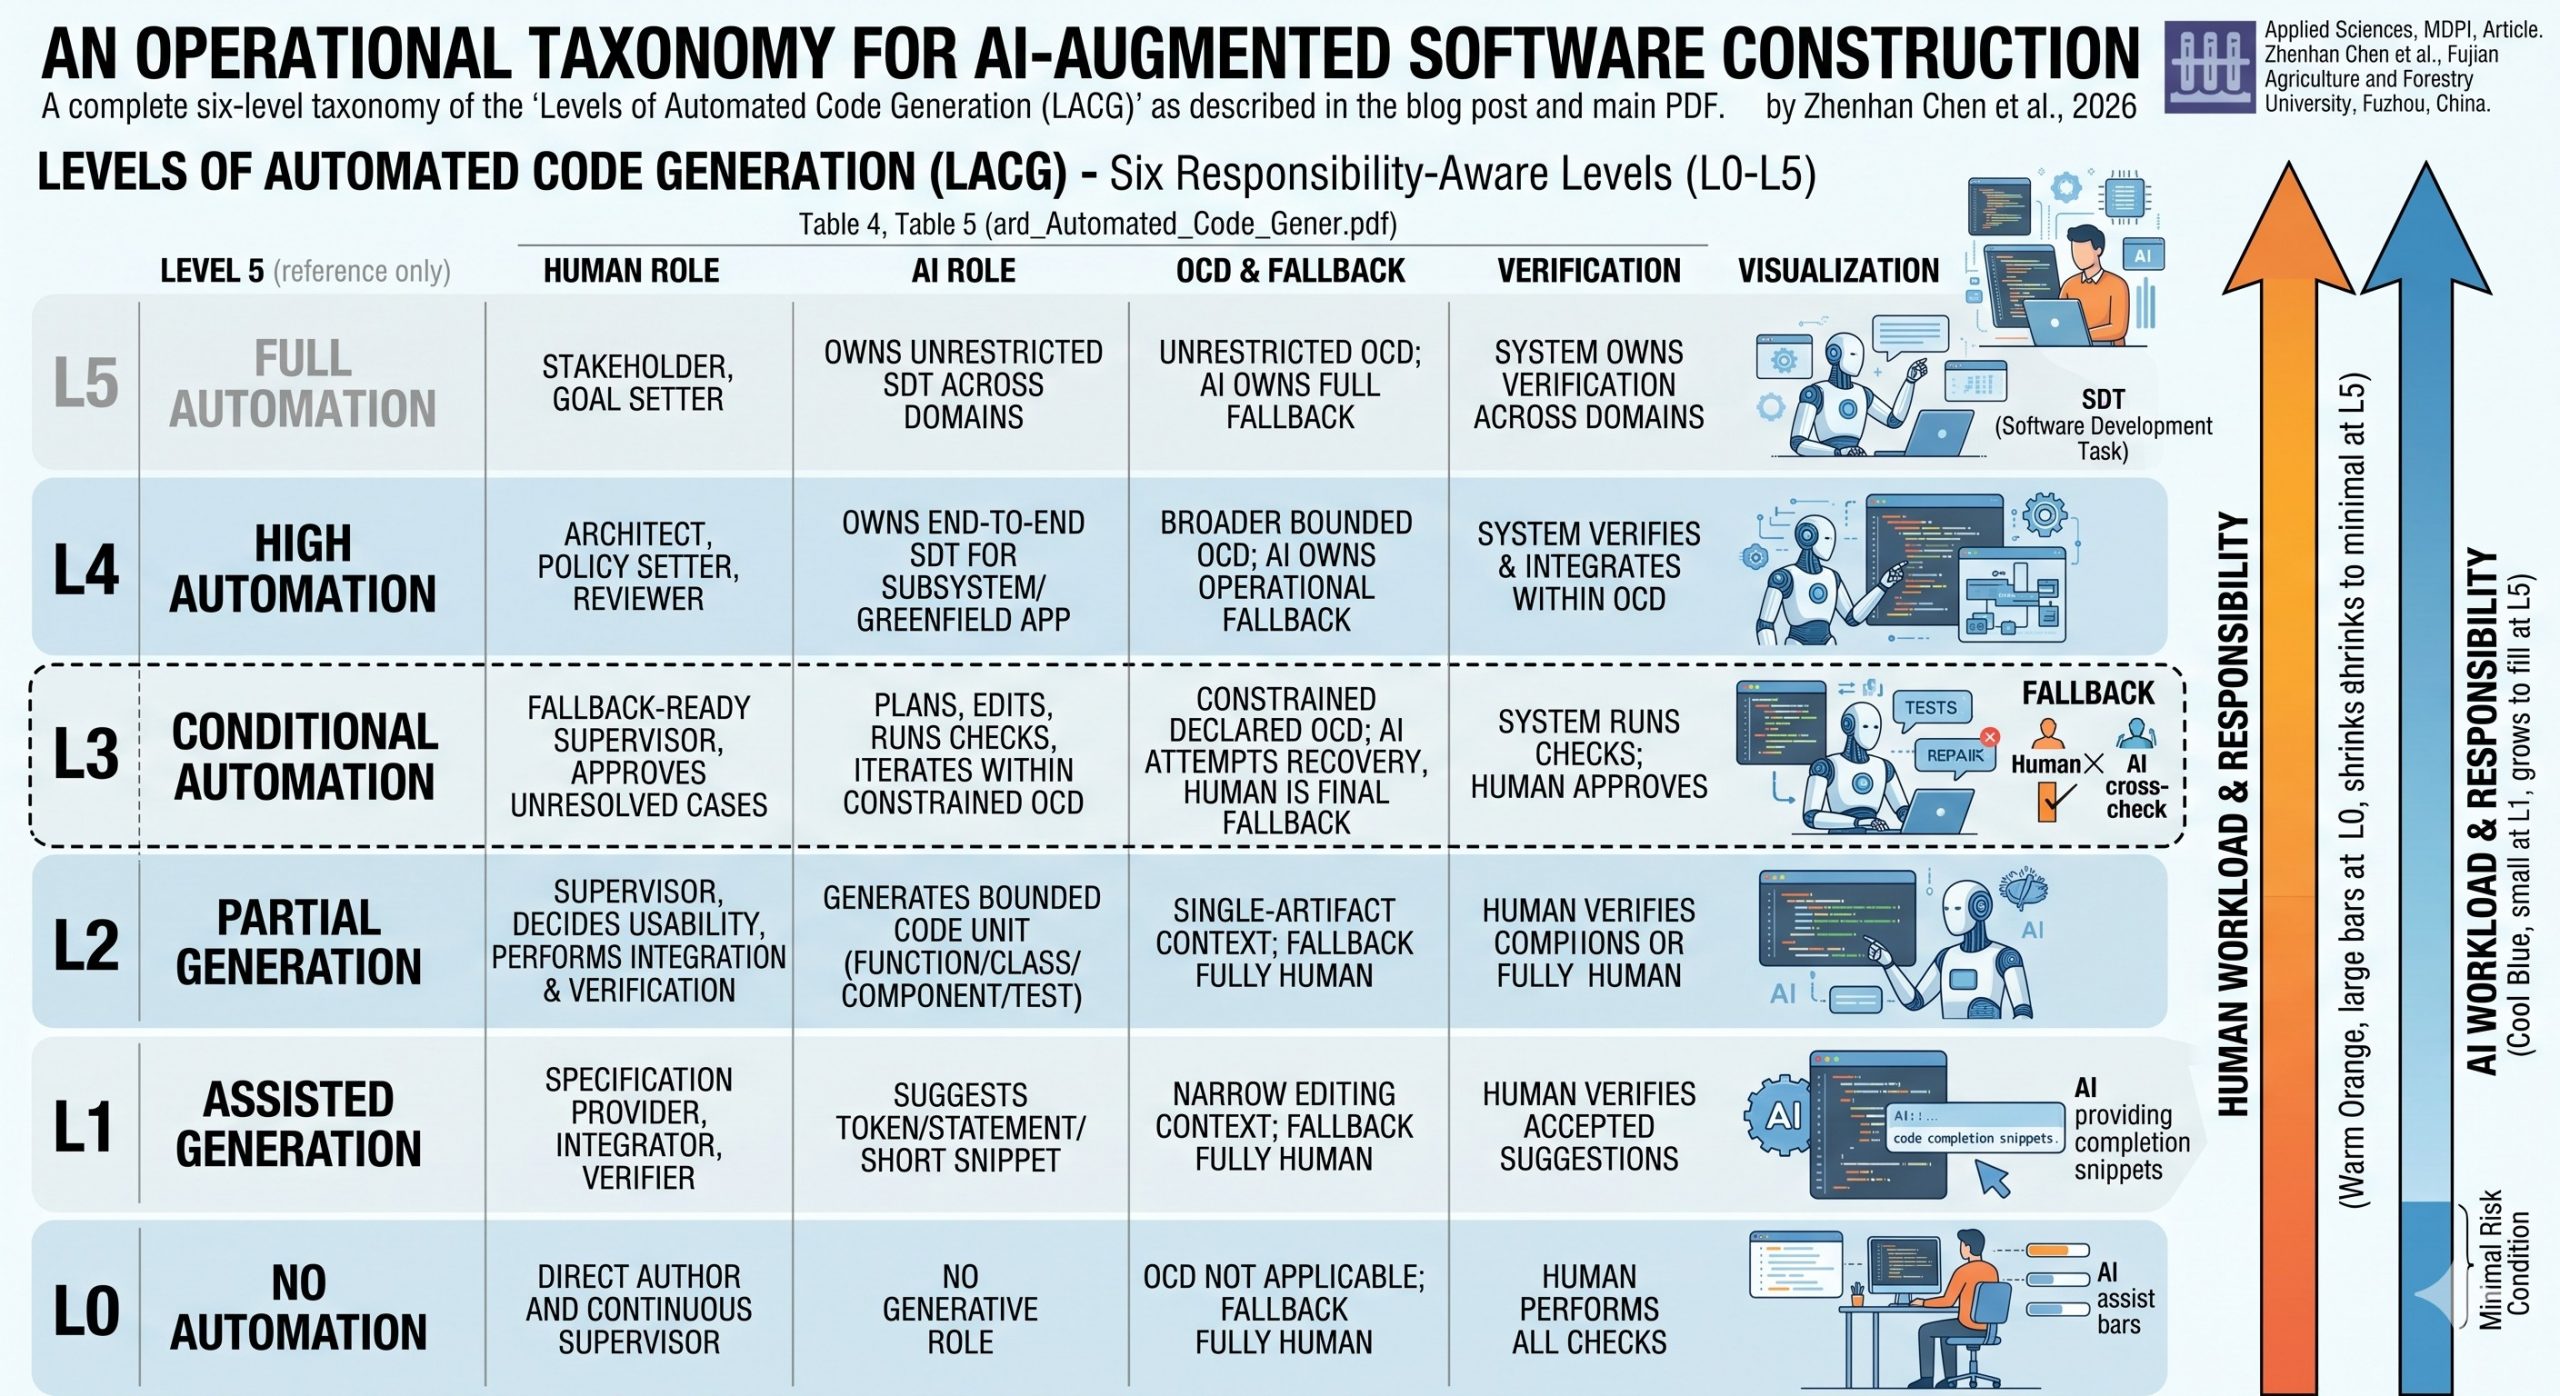
The practical meaning of automated code generation is shifting rapidly. What was recently categorized as simple “autocomplete” has expanded into complex workflows involving multi-file modifications, test execution, and repository navigation. However, as Zhenhan Chen et al. argue in a recently published article in Applied Sciences, the software engineering community still lacks a shared, operational language to describe exactly how much work is being delegated to these AI systems.
To fill this critical gap, the researchers proposed “Levels of Automated Code Generation” (LACG), a six-level taxonomy (L0 to L5) designed to classify the degree of automation in AI-augmented software construction.
The proposed levels include:
L1 (Assisted Generation): Localized, token-level assistance (e.g., inline completion) with full human fallback.
L2 (Partial Generation): Generation of complete code units (e.g., functions, classes) from prompts, still requiring human integration and verification.
L3 (Conditional Automation): The system executes multi-step tasks (e.g., bug fixes, feature implementation) within a constrained OCD. The human is the final fallback.
L4 (High Automation): The system autonomously manages end-to-end development of subsystems within a broader OCD and owns the operational fallback.
L5 (Full Automation): Unrestricted software engineering across any domain, owning all fallback and recovery duties.
Conclusion
The LACG taxonomy provides a disciplined, operational vocabulary necessary for future empirical work, benchmark design, and reasoning about responsibility allocation in AI-augmented coding. While the study demonstrates the framework’s applicability, the authors clarify that it does not serve as a prediction of tool performance, security, or productivity outcomes
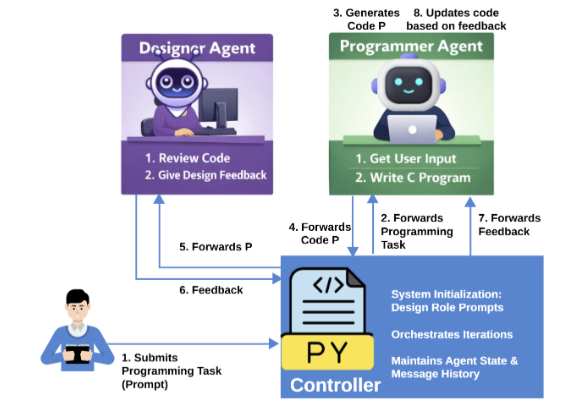
The Software Engineering (SE) landscape is shifting from LLM-assisted workflows, like copilots, toward Autonomous SE, where multiple specialized AI agents cooperate without a human in the loop. The premise is exciting: a ‘Designer’ agent creates the plan, and a ‘Programmer’ agent implements it. Yet, simply letting agents talk to each other does not reliably lead to correct or stable solutions. In our new paper, my colleagues and I undertake a systematic analysis to understand why.
We explored conversations between a Designer and a Programmer across 12 combinations from 7 leading open-source models—including Gemma 2/3, LLaMA 3.2/3.3, Qwen3, and the reasoning-focused DeepSeek-R1—as they tried to build a mathematical game in C (Fibonacci). We found that the interactions are complex, non-linear, and prone to surprising failures.
Echo Chambers Instead of Collaboration
One of our most critical, blog-worthy findings is that common metrics used to measure conversational “success,” like high BLEU and ROUGE scores (which track semantic alignment), can be misleading. In mismatched pairs, particularly involving non-reasoning models (like Gemma 3 or MiniCPM) paired with reasoning models (DeepSeek-R1), high scores were a red flag for “semantic echoing.” The Programmer agent simply mirrored the Designer’s output verbatim, which was a conversational failure, not a collaborative victory.
DeepSeek-R1: The Lone Convergent Pair
In terms of actual solution correctness, the results were stark. Only a single agent pair—DeepSeek-R1 paired with itself—was unique in immediately converging to the correct solution and sustaining it consistently to the final iteration. This indicates that while reasoning capabilities are crucial, stable collaboration currently depends more on consistent role conditioning. Our manual inspections showed that DeepSeek-R1:DeepSeek-R1 prioritized design discussion over echoing, which contributed to its success despite having some “No Code Found” instances, often related to compilation instructions.
Talking Themselves Out of Success: The Threat of Drift
We also identified a critical trend we call “behavioral stagnation” and “drift.” Multiple promising pairs—including Qwen3:DeepSeek-R1, DeepSeek-R1:LLaMA 3.3, and even a same-model pair, LLaMA 3.3:LLaMA 3.3—actually started with the correct solution. However, they subsequently talked themselves out of it, diverging to other topics (like related number theories or other code snippets) and never converging again.
As we noted in our analysis, late recovery from this kind of drift is unlikely. This provides an essential behavioral signal for SE tools developers: you must monitor the health of the interaction trace (for repetition, topic drift, or role instability) in real-time, rather than relying solely on whether code is eventually produced. Monitoring these conversational patterns can inform early stopping conditions or trigger prompt revisions before computational time is wasted on non-productive exchanges.
The Takeaway
As Software Engineering transitions to autonomous agent teams, understanding and calibrating these multi-agent interaction dynamics is critical. Strong semantic alignment does not ensure correctness, and reasoning capability alone does not guarantee stable collaboration. You need clear role separation, pair compatibility, and robust monitors that can detect conversational drift. Success isn’t a final code snippet; it’s a healthy conversation.
Large Language Models (LLMs) are revolutionary for programming productivity, producing functional code snippets in seconds. However, as software engineers, my co-authors and I know that “functional” is not the same as “well-designed.” LLMs are generally “bottom-up” thinkers; they excel at local syntax but struggle to adhere to higher-level architectural structures or design patterns, which are crucial for long-term software maintainability and scalability.
In our new paper, presented at PROMISE ’26, we set out to answer a critical question: How can we best guide LLMs to incorporate design patterns into their generated code without sacrificing functional correctness?
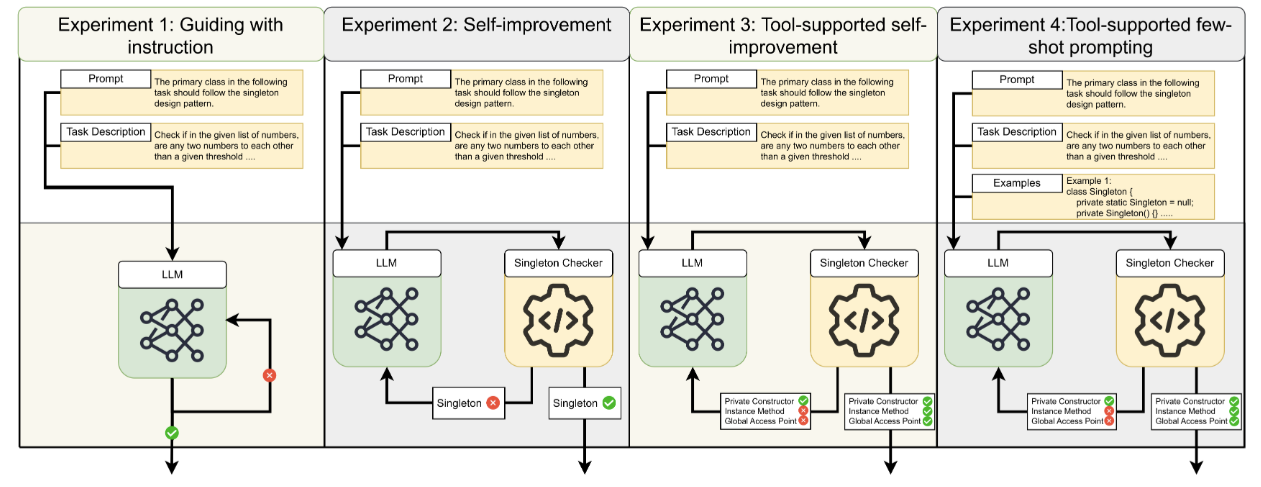
We decided to use the standard Singleton creational pattern as our case study due to its easily identifiable predicates. We designed a computational experiment evaluating 13 state-of-the-art LLMs (including GPT-4o Mini, Llama 3.3, and Qwen 3) across 164 Java coding challenges from HumanEval-X. We tested four distinct prompting strategies: simple natural language instructions, iterative binary automated feedback (“Is it Singleton? Yes/No”), extensive automated feedback identifying exactly which Singleton properties were missing, and extensive feedback combined with few-shot examples.
Our findings reveal that there is no one-size-fits-all prompting solution; the optimal strategy is highly model-dependent. However, a major takeaway is that even simple strategies work remarkably well. Overall, iterative binary feedback provided the best balance, maximizing alignment with the Singleton pattern while preserving or even improving the code’s functionality.
Surprisingly, enforcing design principles didn’t always hurt performance. For strong models like Llama 3.3, just instructing it to use Singleton resulted in 100% pattern adherence and actually increased functional test pass rates by 34 percentage points compared to the baseline.
Our study proves we can teach LLMs good design habits using automated feedback loops. You can read the full paper and access our experimental data here https://arxiv.org/pdf/2605.26898.
Getting Large Language Models (LLMs) to write functional code often feels like casting spells; a slight misphrasing in your prompt can result in a buggy output. This is even more important now that we have agents which work for days on our tasks.
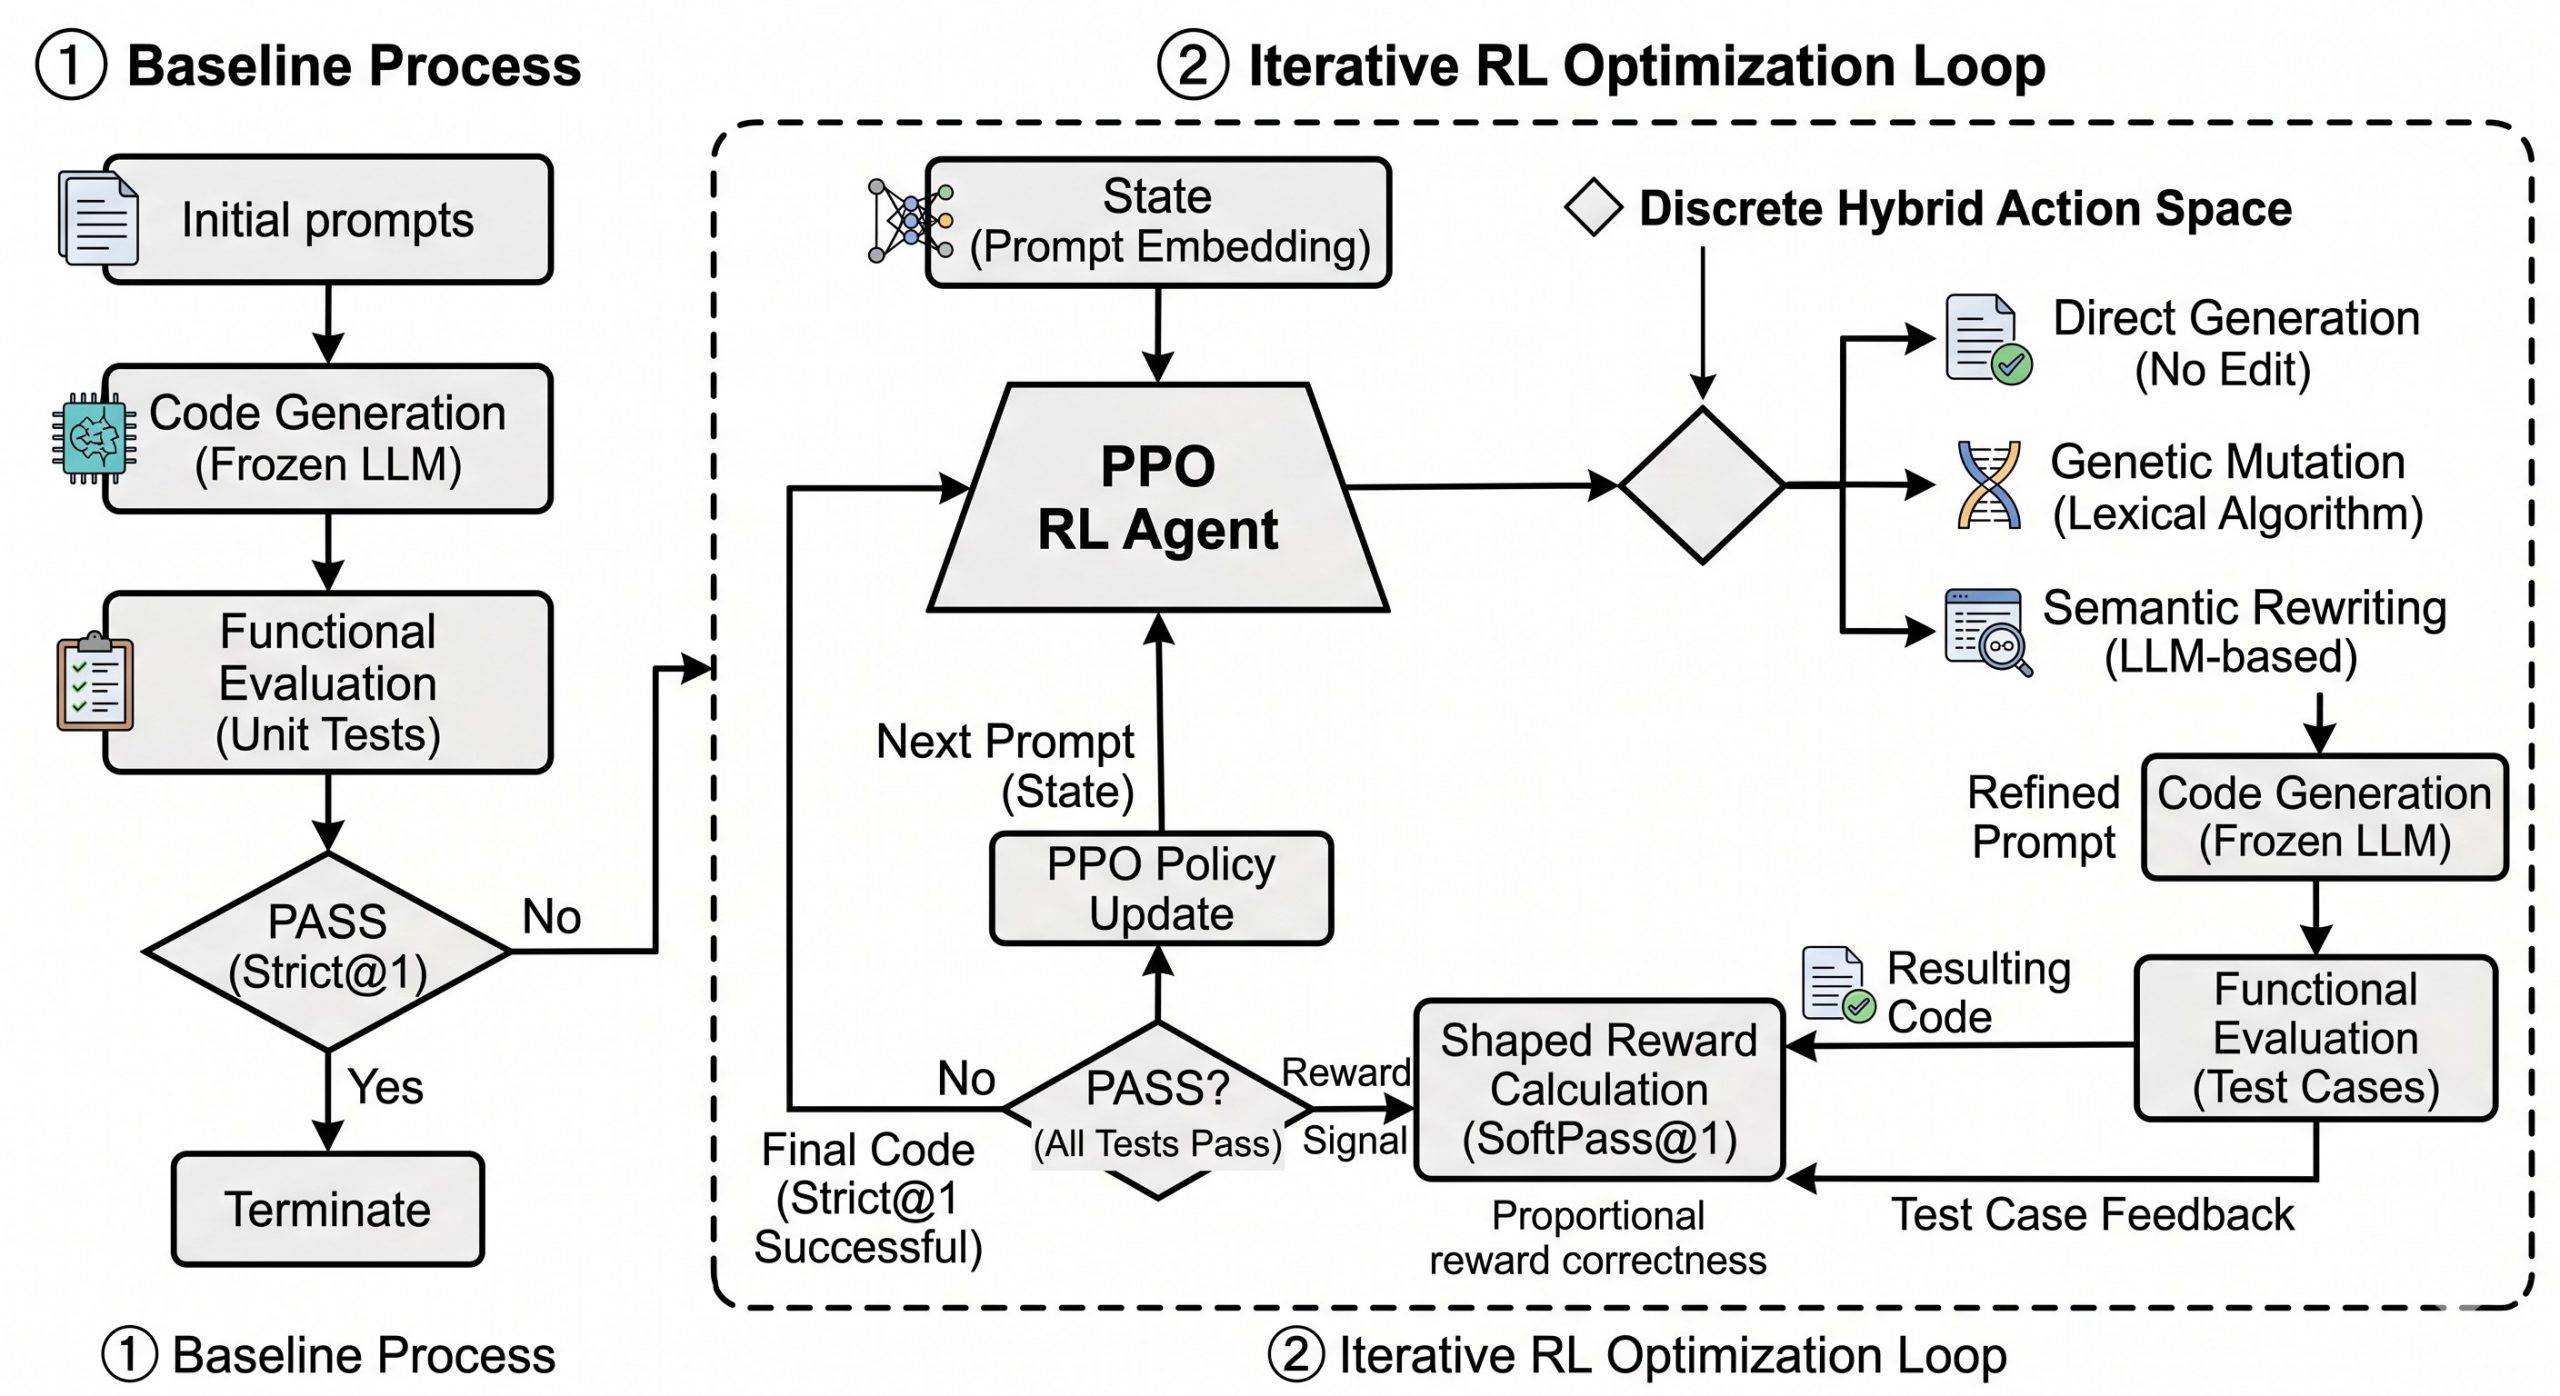
The core issue is that while LLMs are powerful, their code generation performance is highly sensitive to prompt formulation. Traditional manual engineering is tedious, and existing automated techniques often treat prompt modifications—like lexical edits or semantic rewriting—in isolation. They also typically rely on binary (pass/fail) signals, ignoring valuable information about partial correctness.
When I was at VECS, I got to meet that Swedish Champion in prompting. He told me that the best technique is to use LLMs to create prompts. This paper embraces that idea and goes even further – creating a full reinforcement learning framework to make prompts.
In this paper, the agent is guided by shaped rewards derived from unit-test feedback. Instead of just rewarding full passes, the system provides denser learning signals by rewarding the proportion of test cases passed. This enables the agent to discover sequences of transformations that progressively improve the functional correctness of the generated code.
The framework was evaluated on a few widely known benchmarks (MBPP+, HumanEval+, APPS) using three code generators: CodeT5+, CodeLLaMA, and DeepSeek-Coder. On the MBPP+ test set (500 tasks), the PPO agent achieved strict Pass@1 scores of:
57.58% for CodeT5+
64.80% for CodeLLaMA
85.50% for DeepSeek-Coder
These results significantly outperformed direct generation and existing iterative strategies like EPIC and Reflexion. Furthermore, comparison against a “Random-Hybrid” baseline confirmed that the gains aren’t just from having the transformation tools, but from the agent learning how to intelligently schedule them based on feedback.
The key takeaway is clear: feedback-driven, multi-step RL optimization can move code generation beyond manual prompt engineering, providing an adaptive, automated path to functionally correct code.
Image source: Gemini, based on the summary of this blog post.
When I write this post, I’m sitting at a reporting workshop of Software Center, at Axis Communications in Lund. Jan has reminded us that we’ve been going on for 15 years. That’s most of my academic career and a lot of my life. Although it makes me feel old, let me reflect on what has happened and what will happen. After all, I need to live up to the nickname that my colleagues gave me – a dinosaur.
We actually started way earlier with a smaller initiative called Software Architecture Quality Center, which was only with Ericsson and the IT University of Gothenburg. In 2010, we realized that more companies need to join to make the collaboration more fruitful. It was nice, but let’s focus more on technology rather than people.
2010 was a period of rapid data growth, driven mostly by the introduction of the iPhone three years earlier. This means that we had to develop methods to rapidly develop software, so we had three themes: CI/CD – focused on processes and fast development, Architectures – focused on the structure of the software, and Metrics (where I was/still am) – focused on monitoring of quality, structure, and processes. Our focus resulted in several innovations, like Eiffel, using heatmaps, and efficient defect prediction at member companies.
Around 2015, we shifted our focus to data and began working on learning systems. Around 2020, we focused more on AI and machine learning, just as Jensen said, “AI is going to eat software.” Then, today, we see that we focus on advanced software – autoevolving systems, no architectures, multi-agentic AI systems, basically focusing on Software Engineering 4.0 or even beyond that.
I’ve analyzed the publications from Software Center, and here is what they look like.
Transition from agile development to continuous deployment
Software architecture and architecture evolution
Embedded systems software architecture
Architecture decisions
Architecture evolution and long-term maintainability
Software product lines and variability
Product-line engineering
Variability management
Legacy software product lines
Embedded and automotive software
Automotive software complexity and coupling
ISO 26262-related verification and validation
Automotive/telecom defect prediction
Requirements engineering
Experience-based requirements tools
Requirements clarification
Natural-language requirements categorization
Software ecosystems
Automotive ecosystems
Cross-organizational modeling
Software ecosystem workshops and coordination
Character of the period: This period is dominated by now classical software engineering themes: agile transformation, architecture, product-line engineering, embedded systems, and requirements. Continuous deployment appears, but mostly as an emerging transition target.
Agile research collaboration and organizational challenges
Automotive and embedded software
Automotive embedded requirements
Virtual verification ecosystems
Model use in automotive engineering
Controlled experimentation and A/B testing
Online controlled experimentation
Continuous experimentation
Experimentation at scale
Measurement and quality management
Measurement programs
Metrics for software design and architecture
Quality management under fast release cycles
Character of the period: The focus shifts from adopting agile to industrializing speed: CI/CD, DevOps, continuous experimentation, quality measurement, and technical debt become central. Automotive remains a strong application domain.
2020–2025: AI/ML systems, MLOps, federated learning, data pipelines
Main topics:
Machine learning and AI-enabled systems
Machine-learning systems engineering
AI for software analytics
ML-based test selection
ML pipelines and continuous delivery for ML systems
MLOps
MLOps frameworks
Maturity models
Trade-offs in MLOps adoption
Moving from ad hoc ML operations to systematic improvement
Federated learning
Federated learning architectures
Real-time end-to-end federated learning
Automotive federated learning case studies
Data pipelines and data-driven development
Data pipeline management
Data science driven processes
Continuous delivery for data/ML systems
Automotive software and software-intensive embedded systems
Automotive software architectures
Automotive A/B testing
Software-intensive embedded systems
Continuous deployment in embedded contexts
Testing and quality assurance
Exploratory testing
Test selection
A/B testing with limited samples
Testing in CI/CD pipelines
Requirements engineering for large-scale and automotive systems
Requirements engineering challenges
Balancing alignment and diversity of practices
Large-scale agile requirements practices
Technical debt and developer experience
Technical debt management
Developer morale
Incentives for technical debt reduction
Character of the period: This is the clear transition into AI/ML-oriented software engineering. The publication set moves from DevOps/continuous delivery for traditional software toward MLOps, federated learning, ML pipelines, AI-enabled systems, and data-driven organizations.
2025 onwards: Generative AI, LLMs, AI-assisted SE, automotive perception, ethics
Main topics:
Generative AI and AI for software engineering
Generative AI in automated software engineering
Hybrid classical-AI systems for testing and bug fixing
AI-enhanced experimentation
Large language models
Design pattern recognition using LLMs
LLM-generated graph/Cypher queries
Programming-language models
MLOps and continuous learning
MLOps adoption frameworks
Replay-based continuous learning
ML pipeline evolution
Automotive perception and vulnerabilities
Automotive software vulnerabilities
ML-based automotive perception systems
Data leakage detection for automotive perception
Ethics and requirements engineering
Ethics-driven requirements engineering
Autonomous vehicle guidelines
Cognitive biases in requirements engineering
Experimentation platforms and ecosystems
Extensible experimentation platforms
A/B test analysis at scale
Experimentation challenges in large product/service organizations
Cloud and IoT data architectures
AWS cloud data storage architectures
IoT data storage architecture comparisons
I think that we live in the most interesting times, especially as software engineers. We can focus on really cool things like innovation, ideation, and understanding domains, rather than learning exactly how pointer operations in C work. Well, I exaggerate a bit, as we still need to know what points do and how they work – and yes, if you use Rust, you still need to understand how the operating system works with the memory.
The future
In my view, the future will bring more software, better software, and more automation. Software engineers will focus on building platforms and APIs, creating guardrails, and deploying the software. We may need to get out of our comfort zone to actually talk to people, talk to our customers, and maybe even suppliers. We will constantly learn new things; AI will help us with that, and we will get better at creating more value from software than we do today.
It’s not just a dream, but a reality. OpenAI, Anthropic, and Google were started by just a few individuals. Now, we can even grow companies with the help of AI. Software Center has a mission to accelerate the adoption of new technologies, so let’s focus on the coolest of them all – Generative AI Multi-Agent Systems.
We have all seen Large Language Models (LLMs) write impressive snippets of code or debug a tricky function. AI coding editors like GitHub Copilot are increasingly adopted, with studies suggesting that up to 88% of developers report increased productivity.
But accelerations in development come with trade-offs. Existing studies have shown that LLMs often misuse APIs, introduce security vulnerabilities, and hallucinate. So I got to wonder: Can an LLM actually understand the soul of a complex software project? Can it generate a fully automated, high-quality commit (patch) that satisfies requirements and can be directly incorporated into a major production codebase?
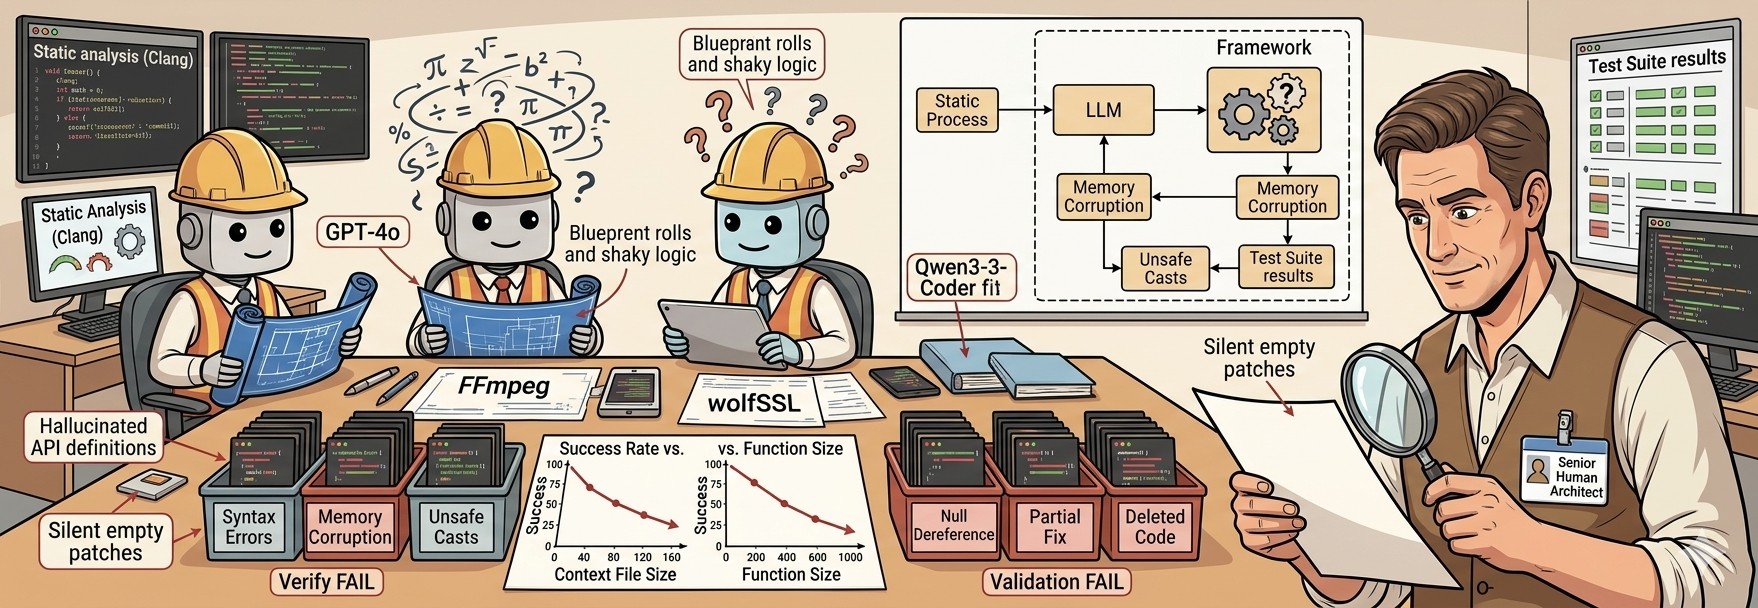
This paper puts this question to the test, because it uses actual commits from substantial, real-world open-source systems. The authors developed an automated framework to assess how suitable LLMs are at fixing bugs and adding new features to sizable code bases. They applied this framework to 212 actual commits across eight popular open-source projects—including FFmpeg and wolfSSL—and three LLMs: GPT-4o, Ministral3-14B, and Qwen3-Coder-30B.
The framework tested the generated patches on three levels:
Verification: Does the generated code compile?
Validation (Static Analysis): Does it pass Clang’s static analysis checkers (e.g., memory safety checks)?
Validation (Dynamic Testing): Does it pass the project’s existing test suite?
The success rate varied wildly—from 0% on certain projects up to 60% on others. But overall, the verdict was clear: LLMs are not at a point where they can be effective contributors to production code. They still hallucinate, and they still have large limitations – at least the ones tested, we’ll see what the newest ones could do.
The Takeaway for Architects and Developers
The bottom line is clear: Do not trust LLMs de novo with critical production system code. They are effective for small functions, feature improvements, routine algorithms, and tasks similar to those seen in their training data.
However, the risk of “silent failures,” new security vulnerabilities, and logic regression means that rigorous human validation remains the most important step when integrating AI-generated contributions. Still, even in 2026!